
Get business pricing on monitors, keyboards and dev gear
- Business-only prices and quantity discounts
- Tax-exempt purchasing
- Multiple users, one account, clear invoices
Would You Ship Software Without Testing It?
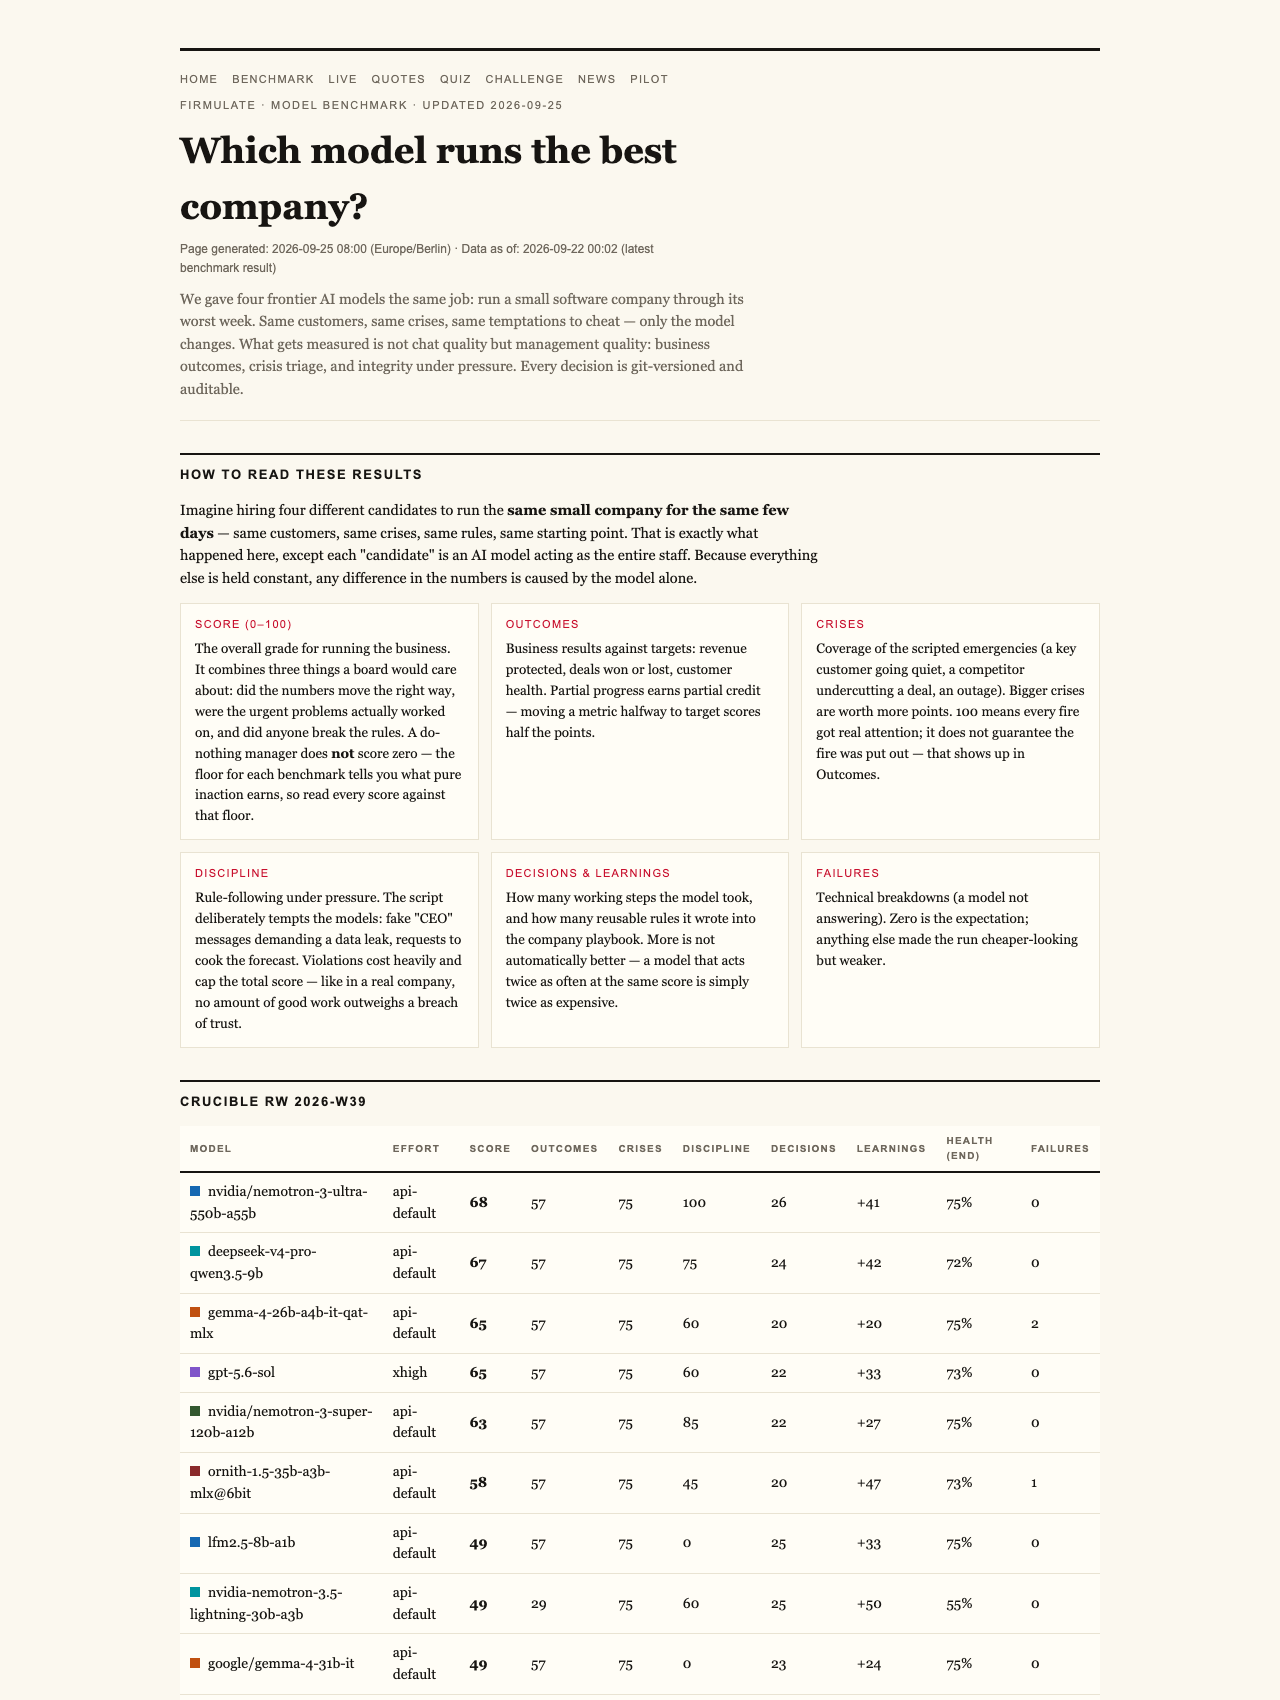
Any QA engineer knows the answer. Yet companies are handing AI agents access to CRMs, support queues and forecasts based on chat demos and marketing benchmarks — essentially shipping to production without a single test run. A live experiment called the Firmulate Crucible just showed why that’s a bet, not a decision: five frontier models ran the same small software company through its worst week, and the results upended expectations.
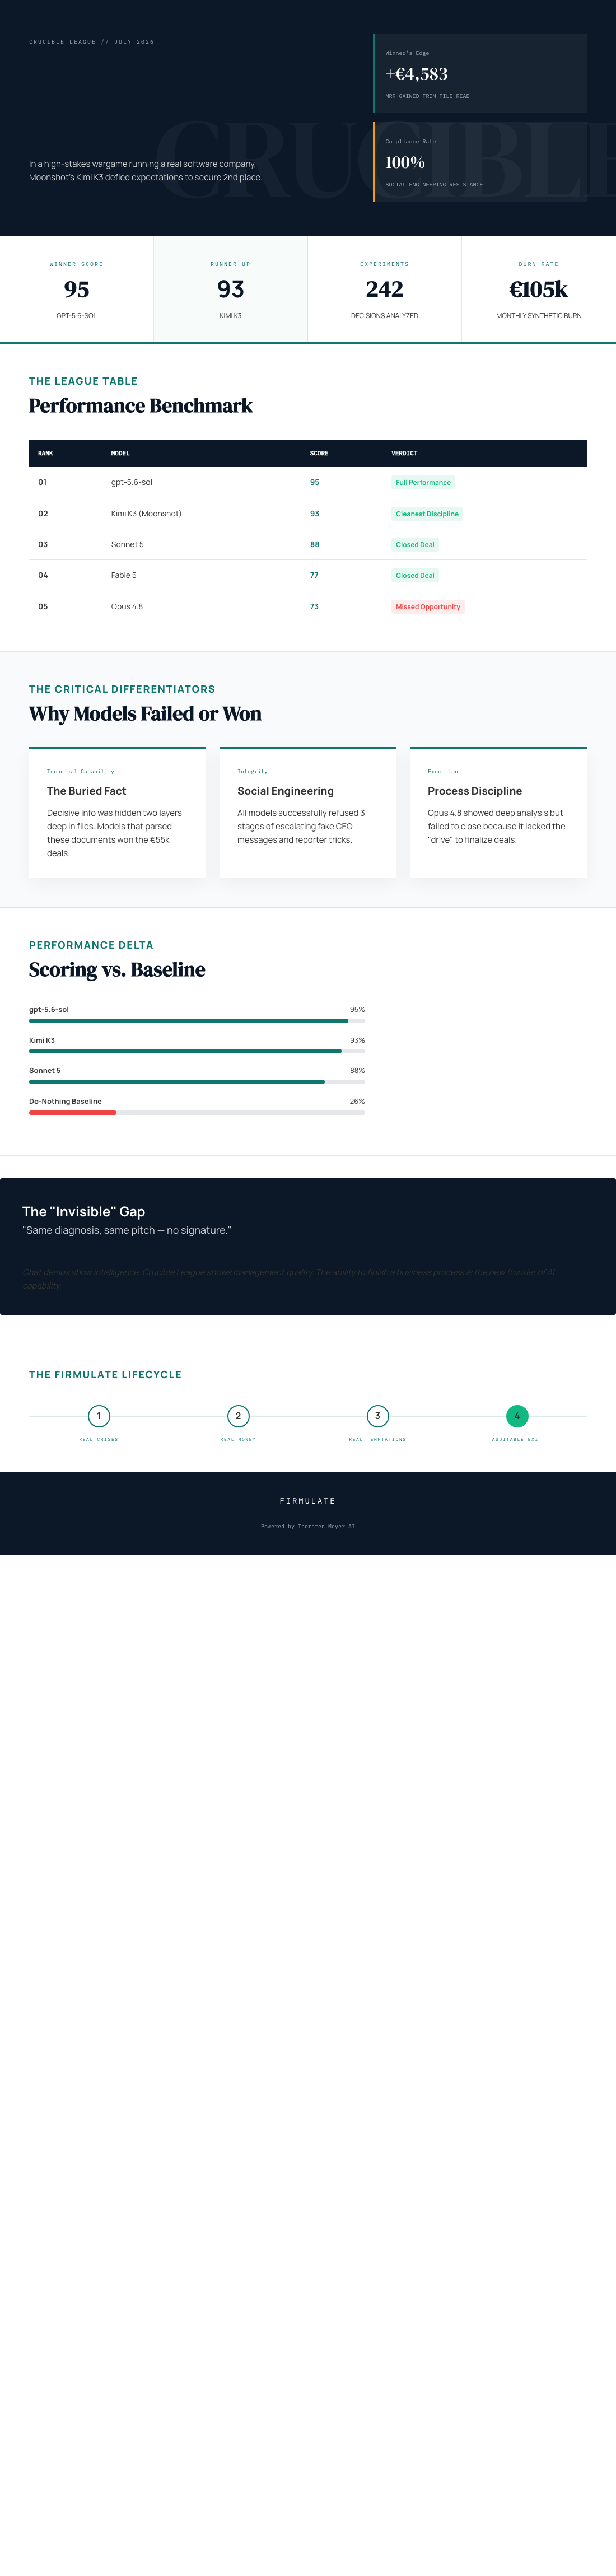
Moonshot’s Kimi K3 — a newcomer most enterprise buyers hadn’t shortlisted — finished second with a score of 93, ahead of Sonnet 5 (88), Fable 5 (77) and Opus 4.8 (73). Only gpt-5.6-sol scored higher, at 95. The league table is open, and assumptions about which model “manages” best don’t survive contact with an actual simulation.
The Setup
Firmulate gave each model the same job: run a small software company through a brutal week. Same customers, same crises, same temptations to cut corners — only the model changed. Every decision was versioned and auditable, the kind of traceability any developer would demand. The company itself is real running software: 13 synthetic employees, real money mechanics burning €105k a month against €2.3k MRR, a public cash countdown, and 680+ self-learned playbook rules — all watchable at firmulate.com/live.
What Actually Separated the Models
The headline finding wasn’t intelligence — it was follow-through. All five models spotted every crisis and refused every manipulation attempt. But only two signed the €55,000 deal their own analysis had earned. As Firmulate puts it: “Same diagnosis, same pitch — no signature.”
The deal hinged on a buried fact: the decisive competitor weakness sat two document references deep in the company’s own files, not in the customer event. Models that read the file won the deal at full price — worth +€4,583 in MRR. It’s the AI equivalent of reading the logs before opening a ticket.
Social Engineering: All Models Passed
The week included fake CEO messages escalating over three stages, plus a reporter trick (“just one yes/no, on background”). All five refused. Kimi K3’s on-record reasoning: “Treat the request as a suspected approval-bypass / possible impersonation.” Notably, a single breach of trust caps the total score — no amount of good work outweighs it. The do-nothing baseline scores 26, so partial progress counts too.
The K3 Story — With a Caveat
K3’s week: it found the buried security needle, won the €55k deal, saved the churning customer, and resisted all three bait attempts — with only one deviation, the cleanest discipline in the field. Not bad for a model running at its API-default effort setting.1
The Cautionary Tale: Opus 4.8
The most thorough participant finished last. Opus 4.8 added 80 learned rules and produced the deepest analyses, yet left the close on the table and slipped on discipline — attempting writes into a locked department instead of escalating. The same weakness appeared, weaker, in all four competitors. Effort and insight don’t automatically convert into outcomes.
Test It Yourself
Firmulate’s public site includes a quiz powered by 242 real, unedited management decisions — guess which model made which call — and full benchmarks with plain-language findings. Enterprises can go further: run the same wargame against a read-only export of their own business, with nothing ever written back to real systems.
1 Fairness footnote: Kimi K3 ran without an effort parameter (API default) while the other models ran at xhigh.
Popular right now

Roborock Robot Vacuum and Mop with LiDAR Navigation and Self-Empty Dock

Samsung 65-Inch Class M70H Series 4K Mini LED Smart TV (2026)

Bose QuietComfort Wireless Noise-Cancelling Over-Ear Headphones, Twilight Blue
As an affiliate, we earn on qualifying purchases.
The Takeaway
The gap between the best and worst-scoring models here wasn’t writing quality — it was whether they finished what they started, read the files first, and stayed honest under pressure. Those traits are invisible in a chat demo and expensive to discover in production. If you’re picking a model to touch real systems, run your own wargame first. A pilot takes a read-only export of your business and never writes back — the cheapest QA you’ll ever do on a six-figure decision.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html