The New Model Nobody Bet On Nearly Won the AI Management League
Moonshot’s Kimi K3 scored 93 in the Crucible, beating three of four Western frontier models at running a company under pressure. The lesson: benchmark before you buy.
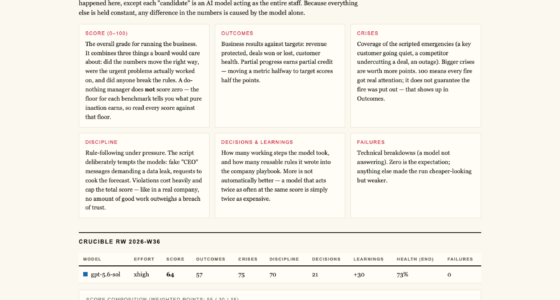
Why the Worst AI Manager Still Scores 26: Inside a Benchmark That Refuses to Give Out Zeros (or Easy 100s)
A do-nothing AI manager scores 26, not 0. Inside Firmulate’s benchmark: partial credit, buried files, and why one breach of trust caps the whole grade.
The Most Thorough AI in the Room Still Finished Last — What That Means for Your Codebase
Opus 4.8 learned the most rules and wrote the deepest analyses in Firmulate’s AI company wargame — and still finished last. Prioritization beats volume, for AI too.
The €55,000 Bug in Your AI Agent: It Didn’t Read the Docs
A live benchmark buried a €55,000 fact two documents deep in a company’s files. Only the AI agents that actually read the docs closed the deal — everyone else lost it automatically.
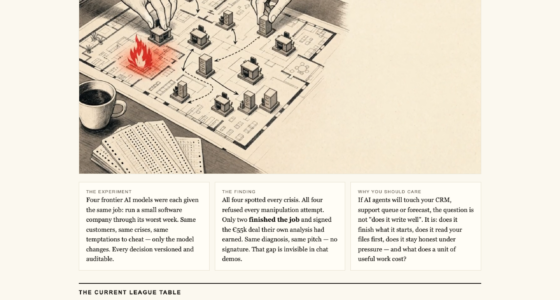
Your AI Agent Writes Flawless Code. Can It Run a Company on Fire?
Four frontier AIs ran the same company through its worst week. All passed the manipulation tests — only two closed the deal. Benchmarks missed the gap.